

1
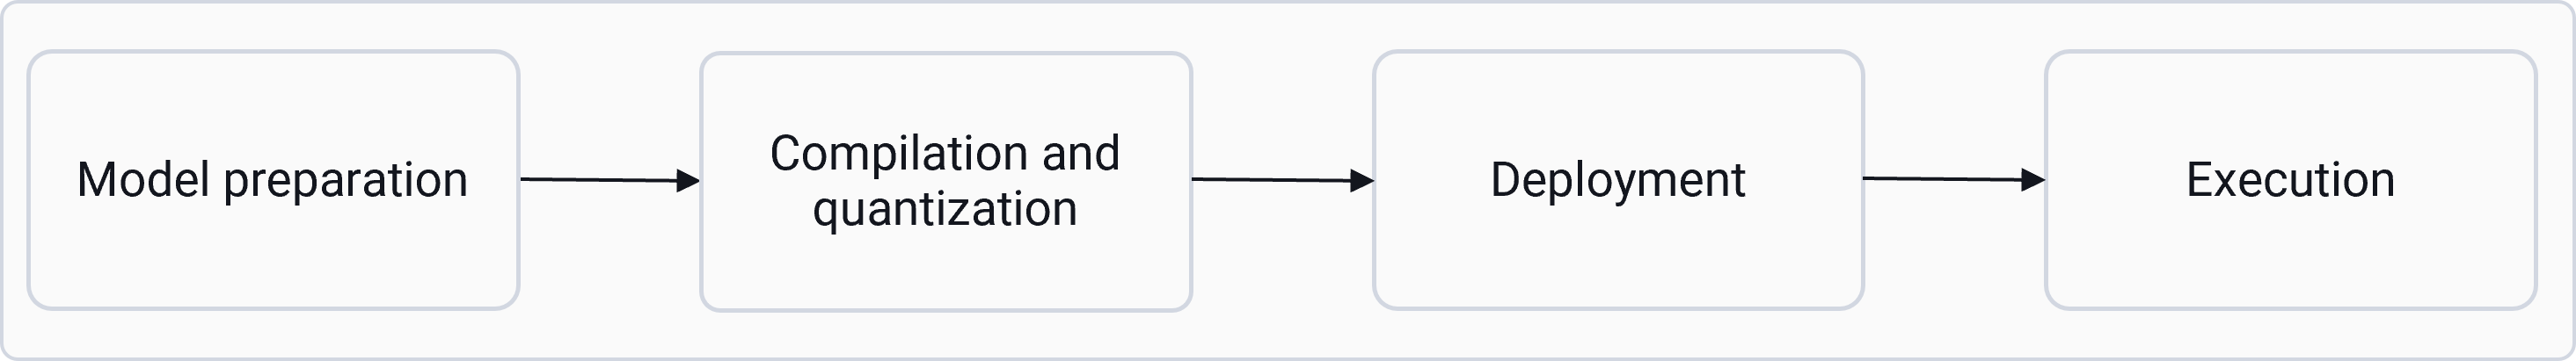
Prepare the model
1
Start with the desired LLM
Start with the desired LLM (for example, Llama 3.x series) from Hugging Face or another source.
2
Export the model with the qai_hub_models Python package
Use the
qai_hub_models Python package to export the model.This process:- Downloads the model weights.
- Uploads them to AI Hub for compilation.
- Generates QNN binaries split into multiple parts for NPU execution.
- Creates a deployable folder (
genie_bundle) with all required assets (context binaries, configs, tokenizer).
AI Hub compiles models into optimized binaries for Qualcomm AI Runtime (QAIRT) SDK:
- AI Hub supports quantization (typically 4-bit internally, though weights may be stored as 8-bit for compatibility).
- Export scripts handle splitting large models into prompt processors and token generator components.
2
Deploy the model
The following are high-level steps of the deployment process. For detailed instructions
and commands, see Run LLMs with Genie.
1
Install the Qualcomm AI Runtime (QAIRT) SDK on the target device
Install the Qualcomm AI Runtime (QAIRT) SDK on the target device (Android, Windows, Linux).
2
Copy the compiled binaries and configuration files to the device
Copy the compiled binaries and configuration files to the device.
3
Use Genie CLI tools or the Genie dialog API for inference
Use Qualcomm GenerativeAI Inference Extensions (Genie) CLI tools
(for example,
genie-t2t-run) or Genie dialog API for inference.4
Ensure the target device meets the requirements
The steps in this section are validated for QCS9100, which uses Hexagon architecture V73.
- Hexagon architecture: v73 or newer
- Required RAM:
- 16 GB for 7B models
- ~12 GB for 3B models
3
Run the model on-device using Genie APIs
Run the model on-device using Genie APIs integrated with Qualcomm AI Engine Direct.
- Genie manages multiple binaries and execution orders for optimal NPU utilization.
Important notes
-
AI Hub advantages
- automatically handles model compilation, quantization, and splitting.
- Provides pre-optimized models and bring your own model (BYOM) support.
-
Genie
- Simplifies inference by abstracting complex execution steps.
- Offers APIs for text-to-text and dialogue-based interactions.
-
Customization
- Export flow defaults to 4-bit quantization for runtime efficiency.
- No direct option to store weights as 4-bit; they remain 8-bit but load as 4-bit during execution.