

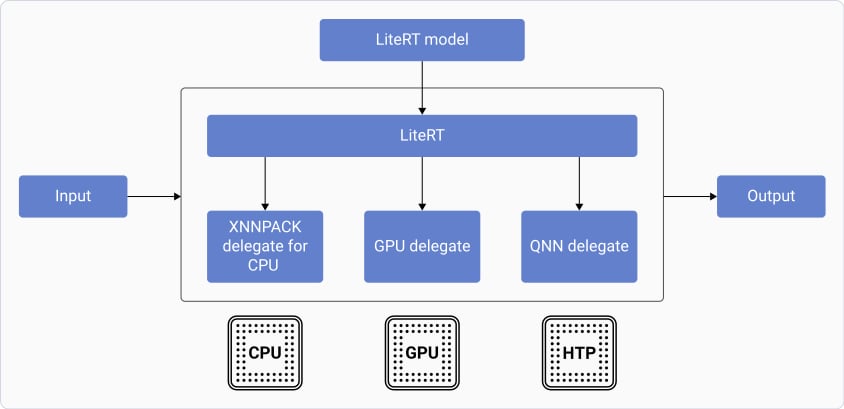
LiteRT architecture
LiteRT on-device inference
The LiteRT on-device inference process loads the model into an interpreter, which parses the model and uses a delegate to run it. The process includes the following steps:1
Load the model into the interpreter
The inference loads the LiteRT model into a LiteRT interpreter interface, which parses the model to identify the neural network operators present in it.
2
Configure the interpreter with a delegate
The interpreter interface is configured to run the model using a delegate.
3
Invoke inference
The interpreter invokes model inference on the provided inputs and saves the corresponding outputs into the buffers provided to the interpreter interface.
- CPU
- Adreno GPU
- NPU